
Intel and SK Hynix Launch Solution to Break AI Inference Bottleneck

 Prefer us on Google


"Relying solely on sufficient GPU computing power is not enough for AI; it must be paired with CPU collaboration for scheduling, management, and execution of AI tasks."
Anil Nanduri, Vice President and General Manager of Intel's Data Center AI Products and Market Strategy, made this statement at the 2026 Intel Seoul AI Summit held on the 12th in COEX, Gangnam, Seoul. Intel announced its AI technology roadmap and industry implementation solutions at the summit and announced the establishment of the K-AI full-stack alliance, with 23 local South Korean companies and institutions joining as the first batch.
Intel believes that as intelligent agents with autonomous planning and multi-task execution capabilities become more widespread, the collaboration between CPUs, GPUs, and dedicated acceleration chips becomes increasingly important. Their approach is to leverage the advantages of different semiconductors to create heterogeneous computing, reducing the cost and power consumption pressure of AI inference—the process by which AI generates output results based on learned content.
SK Hynix is focusing on the storage side to improve data read and write supply efficiency to support this architecture. The company proposed a large-capacity memory pool solution independent of CPU and GPU servers, allowing multiple servers to share resources. To meet the growing demand for AI computing power, SK Hynix is collaborating with customers and partners to validate memory sharing technology and has been working with Intel from the system design phase.
The Vice President and Head of System Architecture at SK Hynix stated in a keynote speech on "Storage Technology and System Design in the AI Era": "In the era of intelligent agents, the value of CPUs is increasing, and Intel's competitiveness is under scrutiny. By redefining the role of memory in systems, we expect to significantly enhance overall performance and energy efficiency."
CPU Responsible for Task Scheduling
Under a single user request, the AI agent needs to complete a series of tasks such as data retrieval, program execution, and result verification. Nanduri said, "Agents need to reason and interact repeatedly to generate answers, which consumes a large number of tokens and increases costs. Infrastructure must be designed according to these task characteristics to improve efficiency and reduce costs."
Intel's Xeon server CPUs are placed at the core of task scheduling. The Xeon 6+, released in the second quarter of this year, integrates up to 288 low-power computing cores, capable of handling numerous tasks simultaneously.
The CPU classifies requests and allocates them to appropriate AI models, managing program operation and security; the GPU runs the models, responsible for generating results; for low-latency scenarios, Intel has introduced dedicated servers from the American AI chip company Samba Nova.
The upcoming inference GPU, Crescent Island, features large-capacity memory and supports simultaneous operation of multiple models. The Intel version is equipped with LPD DR5X, with video memory reaching up to 160GB, while partner versions can go up to 480GB.
Nanduri revealed that a single card has already demonstrated video generation from text, but "the hardware and software have not yet reached mass production standards." Regarding the ratio of CPUs, GPUs, and servers, he stated, "The optimal combination depends on the type of tasks and infrastructure planning."
SK Hynix: Memory Sharing Architecture Reduces First Token Response Time from 80 Seconds to 15 Seconds
As the division of computing units becomes more detailed, the importance of storage read and write continues to rise. However, current HBM is generally deployed in conjunction with GPUs, limiting memory expansion space. The Vice President of SK Hynix stated, "3D stacking technology is still under development, but demand is growing too fast, and customers cannot wait. We are trying to solve the bottleneck from a system level."
SK Hynix proposed a memory rack solution: servers retain their original memory while adding shared memory devices for multiple servers to use. After a GPU completes a round of computation, it stores the results in shared memory before taking on the next task; when that data is needed later, other GPUs can read it directly.
The Vice President of SK Hynix likened it to, "It's like each household having two or three cars versus everyone sharing one car; which is more efficient? This solution improves memory utilization and scalability, achieving overall system cost reduction."
Shared memory can also reduce AI's repeated computations. AI stores intermediate results in KV caches for reuse in subsequent inferences; as conversations lengthen and caches accumulate, local GPU memory can easily run out, forcing the system to delete caches and recompute. By placing caches in independent shared memory, repeated calculations can be avoided.
In comparative tests with partners: the scheme of deleting caches and recomputing took an average of 80.76 seconds to generate the first token; placing caches in external SSDs reduced the time to 33.56 seconds; based on the CXL remote DRAM solution, it only took 15.45 seconds, shortening the response time by about 81% compared to the recompute scheme.
The Vice President of SK Hynix stated, "Reading data from CXL interconnected memory has higher latency than directly connected local memory of GPUs/CPUs, but compared to repeated computations, performance still shows significant advantages."
Expanding to Medical Devices and Unmanned Factory Scenarios
Intel's approach of combining chips and software according to tasks is also being implemented in medical and industrial scenarios. In spaces with limited power supply, achieving AI capabilities with minimal hardware is key.
Samsung Madison relies on the Core Ultra processor's built-in AI computing power and Open VINO software to automatically measure the thickness of ultrasound imaging barriers. Intel claims that this solution does not require a dedicated GPU, and the AI inference throughput is 4.2 times higher than older solutions.
Intel is also collaborating with Daimler Technologies to develop design models for unmanned factories, integrating robots, production equipment, and logistics systems. In the custom chip business, Intel proposed combining customer self-developed designs with its own small chips to flexibly add functionalities.
This summit aims to bridge AI applications and collaborations from data centers and PCs to industrial ends. The K-AI full-stack alliance aims to leverage South Korean local servers, chips, software, and industry solutions to help local customers build and operate their own AI systems.
Santosh Viswanathan, Vice President and General Manager of Intel Asia Pacific, stated, "One of Intel's advantages is helping partners' innovations reach the global market. We can also collaborate closely to supply Korean companies' products to customers worldwide who have demand."
-- Price
This content is provided for general informational purposes only and doesn't constitute financial, investment, legal, or tax advice. Any events, rewards, online promotions, or related information mentioned herein should not be considered a recommendation, solicitation, or invitation to purchase, sell, trade, or otherwise deal in any crypto assets. Crypto assets are highly volatile and may result in loss. The availability of WEEX services, products, and related events may vary by region. You are responsible for ensuring that your participation is in accordance with applicable local laws and regulations.
You may also like

Unocoin Submits Investigation into BitGo Ethereum Address Withdrawals
Trump-linked stablecoin replaced by USDC on FIFA partner's site

The Next Battle in Crypto Security: How to Rebuild the Authorization System Beyond Smart Contracts?
Judge Rejects Novig's Injunction Request, Criticizes CFTC Order for Implying Collusion
Dutch Court Rejects Jaguar Land Rover's Evidence Preservation Request, BYD Achieves Interim Victory in Overseas Intellectual Property Defense
Novig loses court shield, and New York gambling laws strike back

Google Launches Gemini Decisions API Charging $0.10 per Million Input Tokens with 150-250 ms End-to-End Latency
Texas Grid Chief Seeks Authorization for Data Centers to Reduce Power Usage Ahead of Emergency Declaration
Are GOPAX Withdrawals Still Paused? What Users Can Request and What Remains Unconfirmed
Check the latest GOPAX withdrawal status, which wallets qualify for manual requests, and how to tell whether your crypto withdrawal has been sent.
White House Warns House Democrats That Investigative Actions May Constitute Crimes
Bitcoin Scam on Shaadi.com, User Solicited for a $500 Deposit
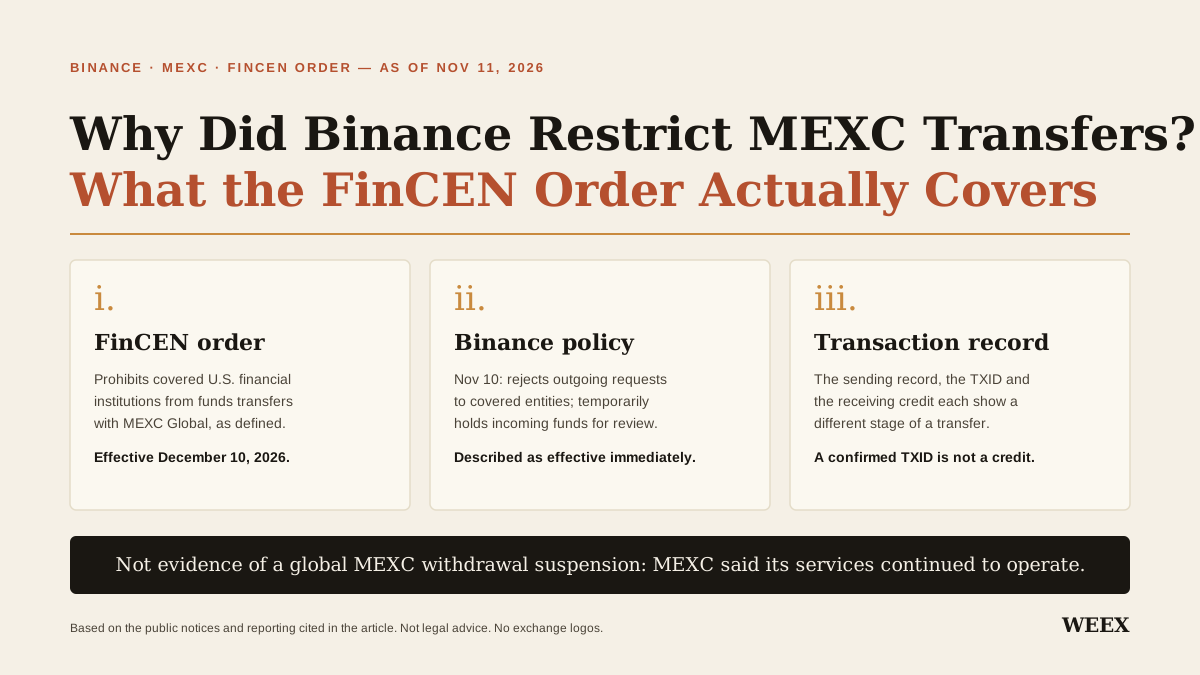
Why Did Binance Restrict MEXC Transfers? What the FinCEN Order Actually Covers
Find out why Binance restricted MEXC transfers, when the FinCEN order takes effect, and what to check if your crypto deposit is held for review.
Head of Turkey's Banking Regulator Requests Resignation as Fund Scandal Investigation Expands
NVIDIA Scandal Shakes the Internet! How Should Cryptocurrency Be Divided After a Divorce with a Tech Tycoon?
Crypto ATM Fees: How Much Bitcoin (BTC) Do You Get for $100?
See how much Bitcoin $100 buys at a crypto ATM. Compare two sample quotes, calculate the all-in cost, and learn which fees not to count twice.
NEAR AI Discloses SGLang Security Incident and Revokes Exposed API Keys

Cash App Founder Bob Lee's Killer Sentenced to 16 Years to Life in Prison
New York Judge Rejects Novig Injunction, State Gambling Laws Apply to Its Market
Arcus Loses $2.23 Million Due to Accounting Flaw, Fully Reimbursed
Miami-Dade To Accept Bitcoin For Property Taxes
Cardano’s police evidence system could bring 1.5 million annual transactions
Coinbase, Kalshi, and Kraken Support CFTC in Court Dispute Over Perpetual Stock Contracts
Unauthorized Access to Gnosis Pay's Old Card System Leads to Customer Data Breach
Westpac's Cryptocurrency Payment Limit (A$10,000): What Changes on December 1, 2026
Meta Releases Muse Ember Model, Supporting 1 Million Token Context
Blockchain.com Adds Trading API for Institutional Crypto Execution
LNbits disables hosted Bitcoin services with no restart timeline
MEXC CEO Establishes Communication with FinCEN and Receives Confirmation
Trump Warns AI Company CEOs of Criminal Prosecution
Solana publishes 11 startup ideas spanning AI and housing futures
Unocoin Submits Investigation into BitGo Ethereum Address Withdrawals
Trump-linked stablecoin replaced by USDC on FIFA partner's site
The Next Battle in Crypto Security: How to Rebuild the Authorization System Beyond Smart Contracts?
Judge Rejects Novig's Injunction Request, Criticizes CFTC Order for Implying Collusion
Dutch Court Rejects Jaguar Land Rover's Evidence Preservation Request, BYD Achieves Interim Victory in Overseas Intellectual Property Defense
Novig loses court shield, and New York gambling laws strike back
Latest articles




Latest coin listings on WEEX


